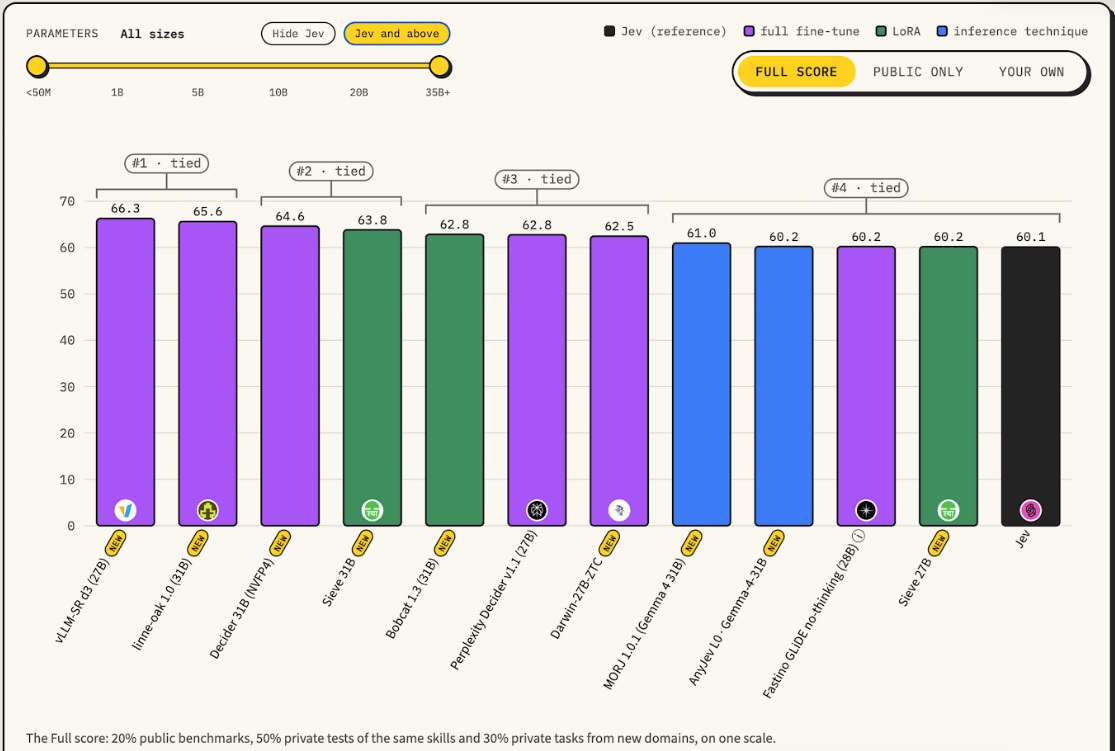
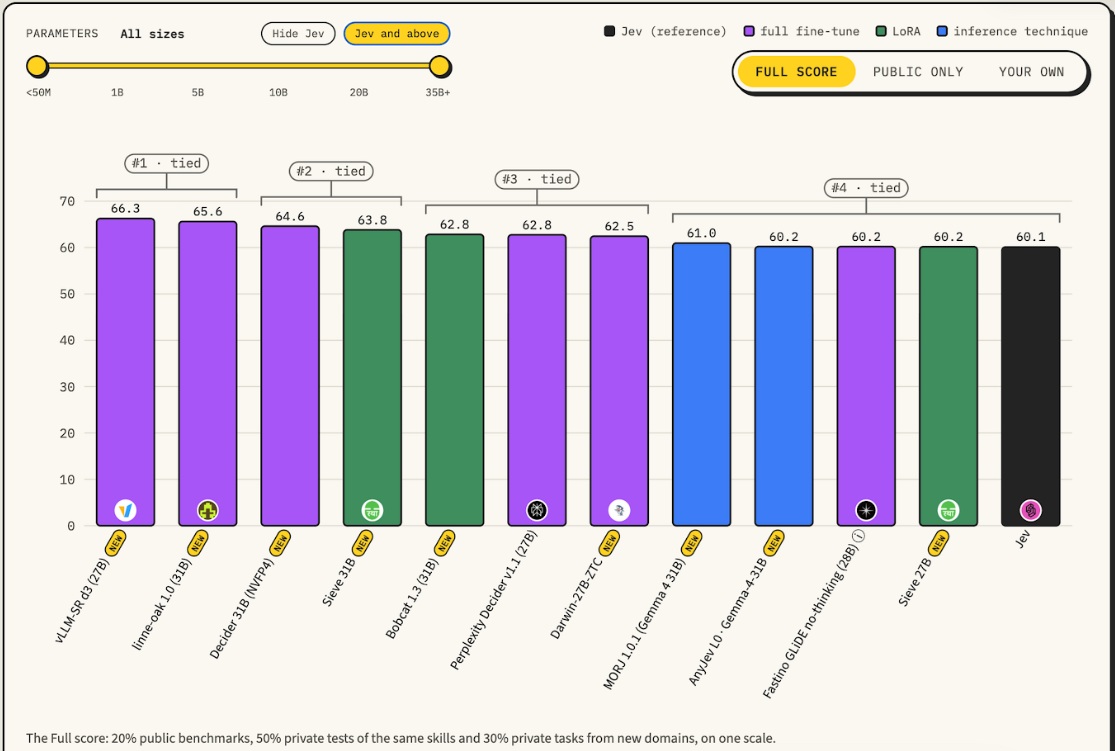
Sthanika, the applied AI research lab of the PurpleTalk group, today announced that its Sieve 31B model has ranked second globally on the Jev Decision Index, an open benchmark hosted on Hugging Face for AI models built to make rapid decisions. Sthanika’s decision models ranked ahead of Jev and Perplexity Decider v1.1
 |
Indian Lab Sthanika’s Sieve 31B decision model ranks second in the Jev Decision Index
Sieve 31B recorded a Full score of 63.8, combining the public test suite with private tests run by the benchmark’s maintainers. It ranked second on the public tests with a full score of 62.5.
Sthanika’s Sieve 31B is a cost-efficient decision model that agents can call as one component in a larger system, and it makes decisions more reliably than general-purpose large language models. Many AI agents today send every task to an LLM, including planning and routine decisions that a decision model can handle more cheaply. That cost grows as agents take on more of the work people used to do. General-purpose LLMs are tuned to converse with people, which makes them the right tool for language and an expensive one for choosing between defined options thousands of times a day. Comparatively, a decision model is extremely inexpensive for those tasks.
The wider Sieve family includes Sieve 2B Plus, Sieve 4B and Sieve 9B Plus each placed among the top in their size classes on the same leaderboard. Developers can run smaller models on their own on-premise GPUs for everyday tasks that need privacy and handle large volumes of work, and switch to bigger, more powerful models when tasks require more advanced capabilities.
Most AI conversations are about models that write, summarise and converse. Much of the AI inside real software does something less visible: it makes small decisions, thousands of times a day. Sieve is built for that decision-making. It reads the question and the available choices as they are presented, then returns a defined answer with a confidence score that software can inspect and act on. That suits applications where consistency, speed and the ability to audit each decision matter as much as accuracy.
“Sieve 31B shows that a focused model fine-tuned in India can perform among the best in the world at this work. The private tests matter most to us. They come from domains outside the public suite, and Sieve generalised better than most of the field. It learned the task, not the test.” said Sridhar Muppidi, Co-founder of PurpleTalk.
Sieve builds on Sthanika’s earlier work on compact, confidence-aware decision models, which already run inside PurpleTalk products including Ello and Mina. There they handle routine judgements faster and more economically than general-purpose generative models. The lab also expects to create a new category of agentic systems which have higher reliability, more granular control, as well as low latency in areas like voice, customer experience, and robotics.
“We believe decision models will open up a new category of agentic systems: more reliable, more controllable and fast enough for voice, customer experience and robotics. We are publishing everything needed to reproduce our results, and we invite the research community to test it, challenge it and build on it,” said Bharat Lingam, CEO & Co-founder, PurpleTalk.
Models and evaluation artifacts: link.
Full results: Jev Decision Index.
About Sthanika
Sthanika is a Hyderabad-based AI research lab that builds open-weight models for problems the general-purpose models were never built to solve. Its name is Sanskrit for “local.” Sthanika is part of the PurpleTalk group. Learn more at sthanika.ai.
About PurpleTalk
Founded in 2008, PurpleTalk builds AI companies and services. The group has worked across sectors like healthcare, agriculture, financial services and retail. Its portfolio includes (x)cube LABS, Sthanika, Ello and Mina.